Crossref members register around 37,000 records daily. All this metadata is openly shared with the global scholarly community through our free APIs. We receive over two billion calls to our API each month, signalling its use by hundreds of tools and services worldwide, supporting the discovery and assessment of scholarly metadata. As part of a new series in our blog, we will spotlight the diversity of tools and integrations that rely on Crossref metadata to serve the scholarly community. In this initial post, we chat to Luca Foppiano, the developer and maintainer of Grobid1, to learn about how Grobid uses Crossref metadata to improve the extraction and enrichment of bibliographic information from scholarly PDFs.
On behalf of the Nominating Committee, I’m pleased to share the slate of candidates for the 2026 board election. Every active member organisation is invited to submit a ballot to elect the incoming board class.
We’re providing a summary of the board’s July 2026 meeting. The July board meeting is our only in-person meeting. The board gathers for two days of strategic thinking and long-range planning, as well as conducting annual board business. This year, we focused on allocating surplus funds we have on hand to invest in a three-year project to redesign the content system. In a related discussion, we decided to lower content registration fees starting in 2027 because we’ve had a demonstrated history of generating surpluses, exceeding what we need to run Crossref. We also discussed the board structure, as part of our regular review of stakeholder governance. And we conducted annual board business, such as approving the audited financial statements and reviewed our risk register and mitigation plans.
The resolutions are available on the dedicated section of our website, which also lists the members of the Board and offers further information about our governance.
We also managed to squeeze in watching a World Cup game over dinner.
Starting today, funder names deposited in Crossref metadata without an identifier will be matched to ROR IDs, to support an open and connected Research Nexus. Funding information is an increasingly important part of the scholarly record. The improved matching strategy supports researchers, funders, institutions, and meta-researchers, who rely on that information to understand how research is supported and what outcomes that support produces.
Research is rarely limited to a single contributor performing a single role. Behind every research output are people contributing in various ways: software development, data analyses, methodology design, and much more. Often, the same person contributes in several of these ways. Until now, Crossref metadata could only capture part of that picture, but this is changing with Schema 5.5.
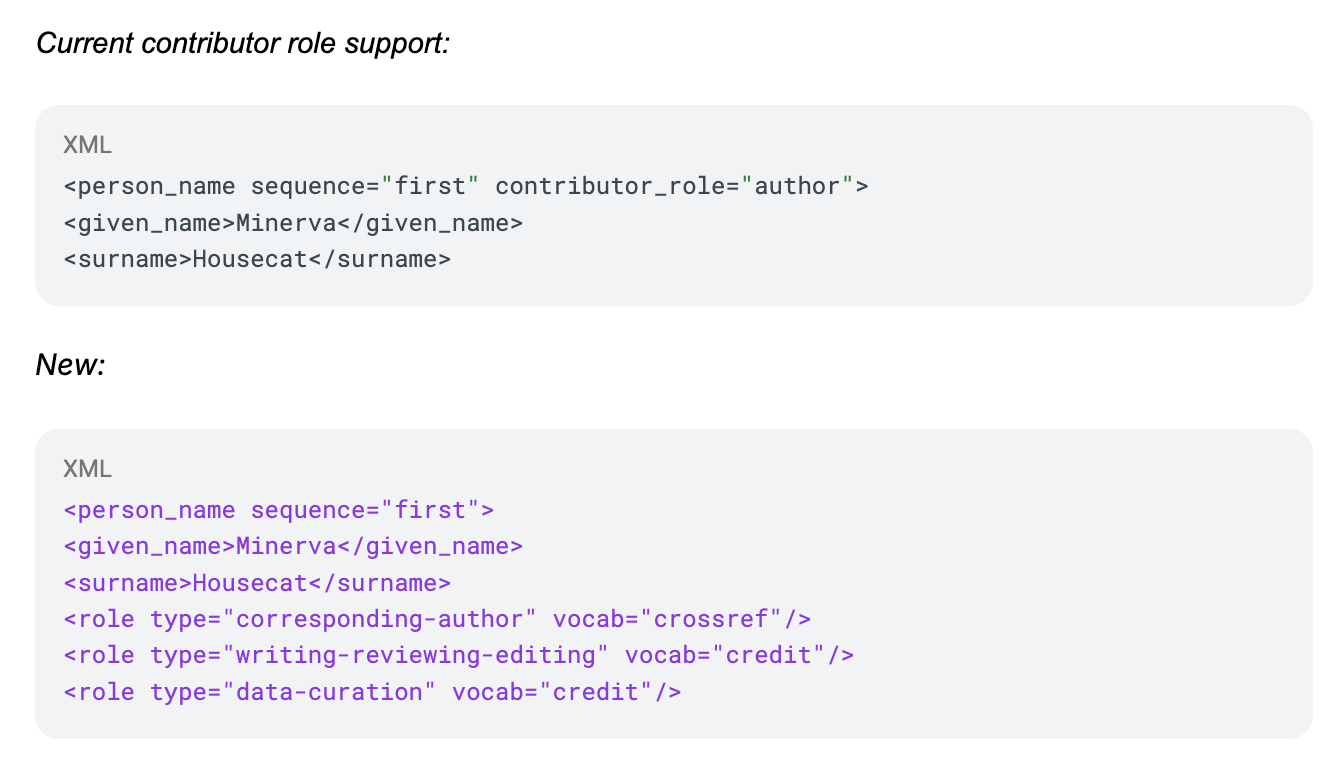
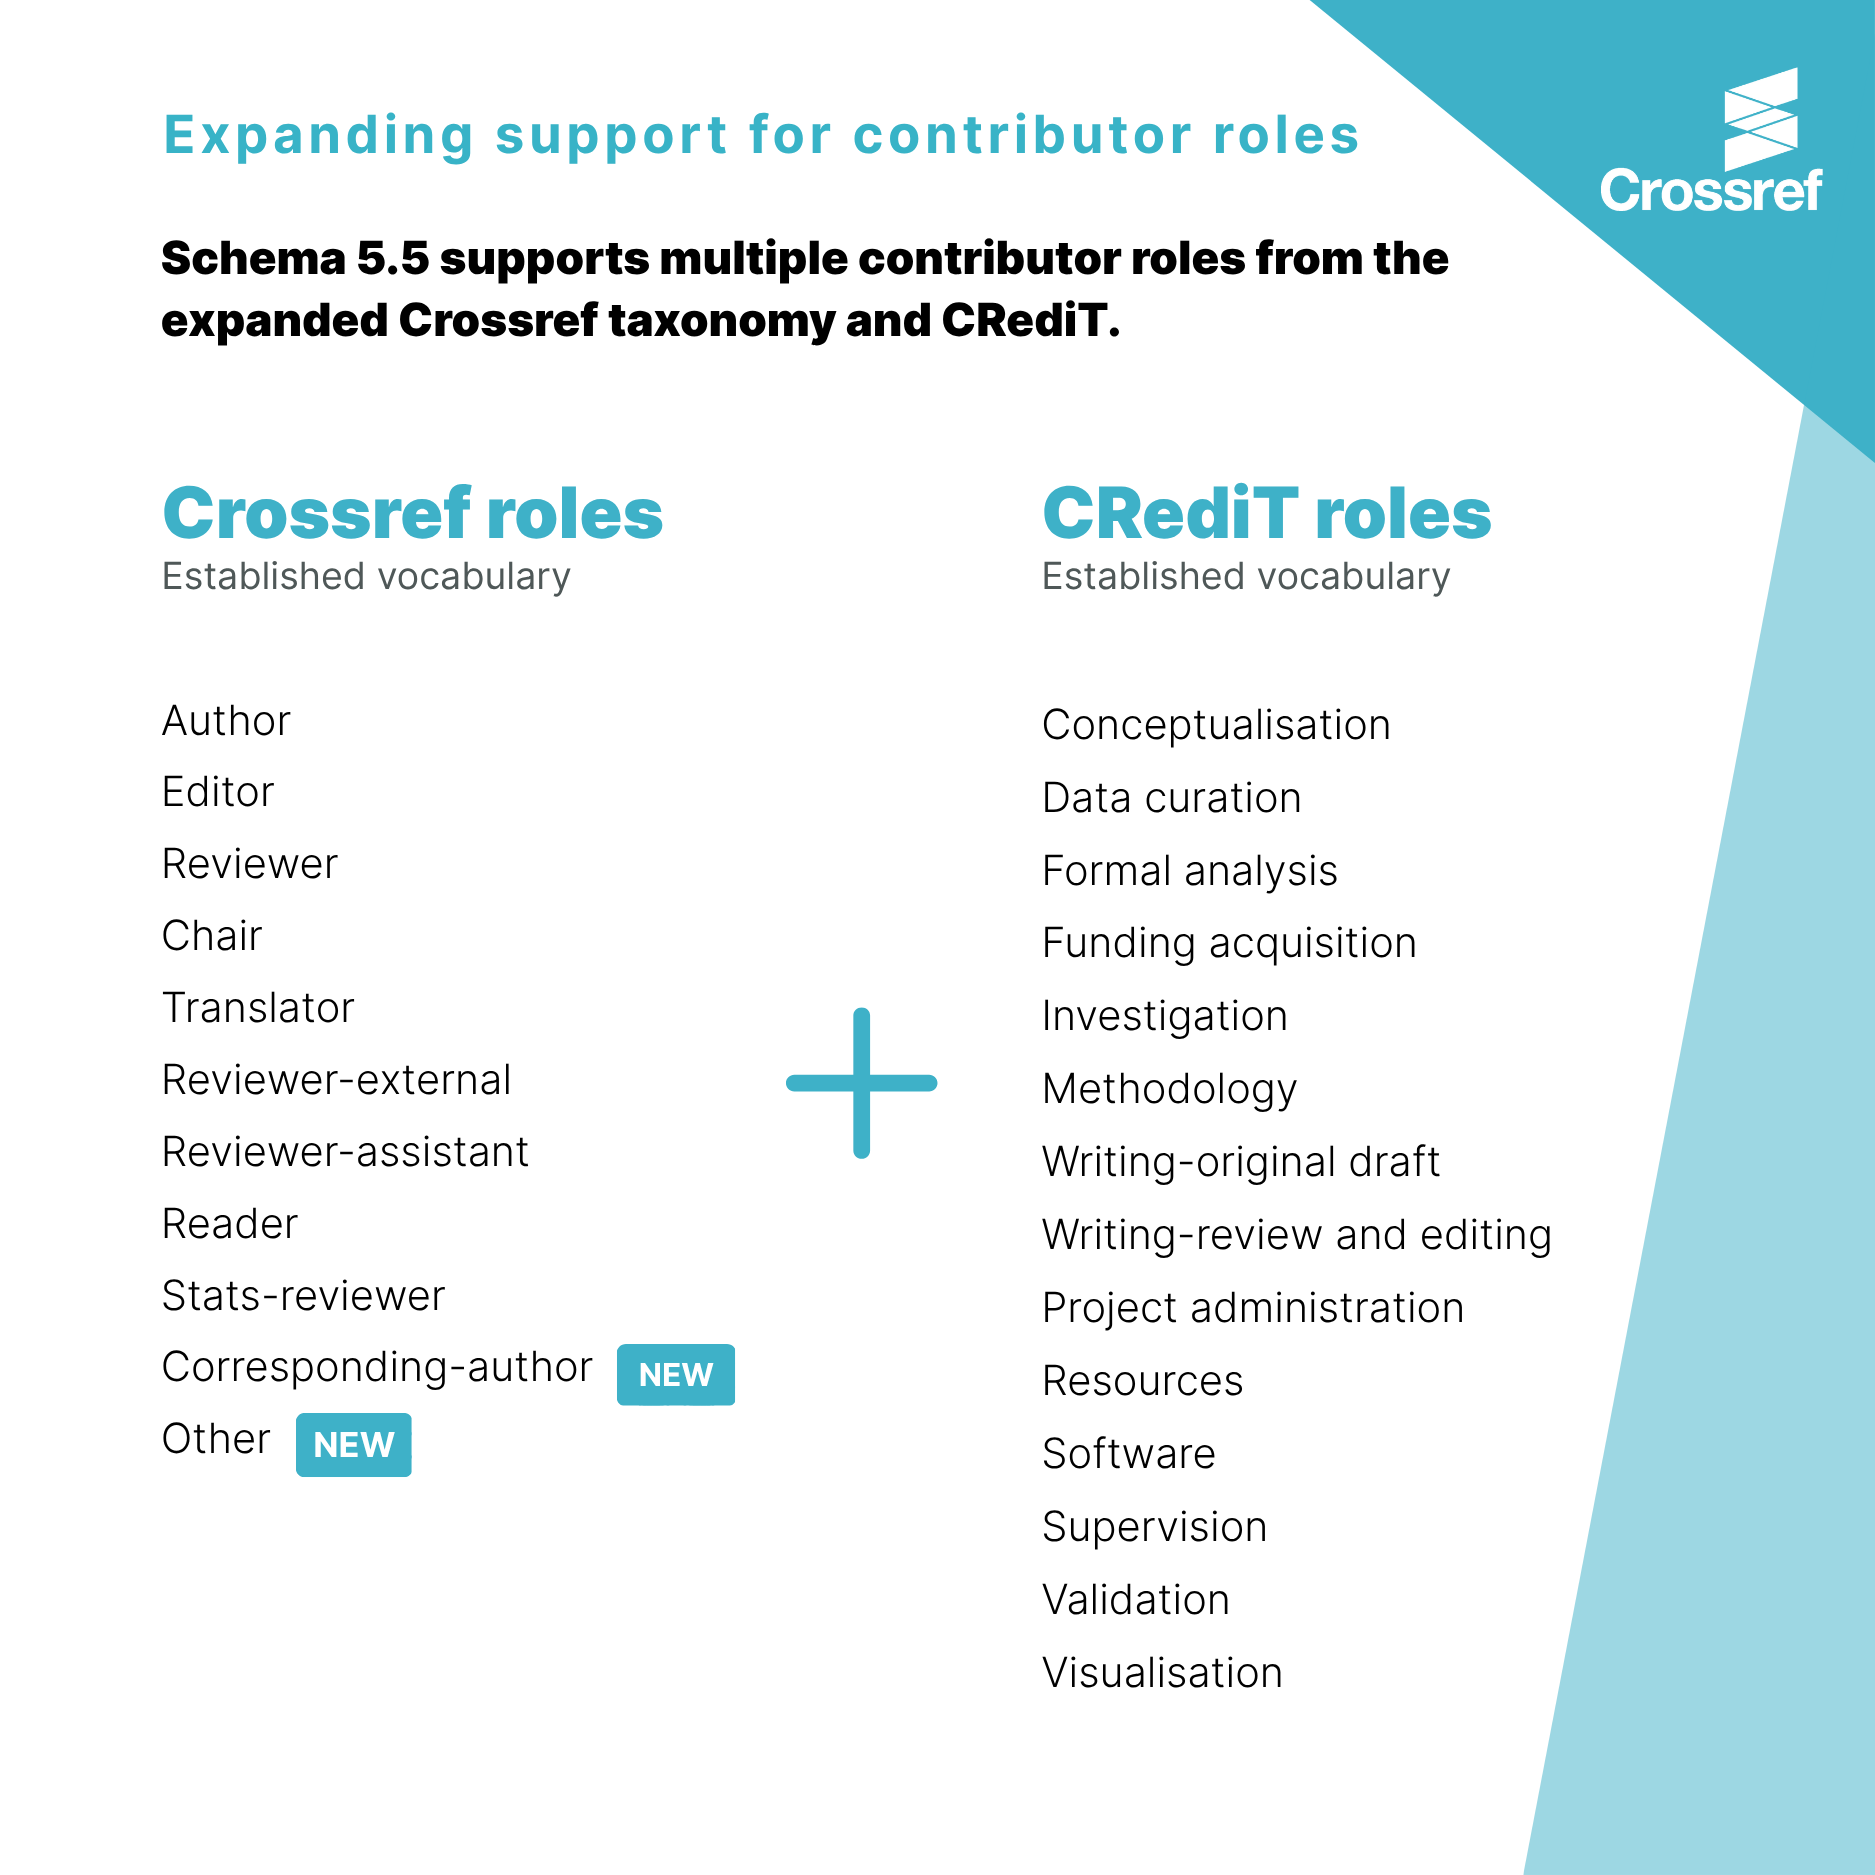
Crossref Schema 5.5 includes several improvements across different content types, but its most significant enhancement is the expanded support for contributor roles through the introduction of multiple roles per contributor, option to specify the corresponding author, and compatibility with the CRediT (Contributor Roles Taxonomy): a community-owned taxonomy of 14 contributor roles, which has been adopted and made available in multiple languages.
These enhancements allow members to describe research contributions in much greater detail, creating richer metadata that better reflects how research is actually produced, and supporting greater accountability and more comprehensive research assessment.
If your workflow already distinguishes between different kinds of contributions, Schema 5.5 gives you a way to record that detail more accurately using the CRediT taxonomy values. CRediT can be adopted gradually, where it fits your editorial or production workflow.
Figure 1: Until now, contributors could be assigned a single contributor role using Crossref’s existing contributor role vocabulary. In Schema 5.5, members can indicate that the same contributor was responsible for different roles, such as corresponding author; writing: reviewing and editing; and data curation.
Existing deposits remain fully supported, and members can continue using the current contributor role attribute while planning implementation of the new repeatable role type element. For our members, who have been using CRediT in their workflows already, as ever – we encourage updating your metadata when practicable.
Why this update is kind of a big deal
This update gives more accurate credit to all of the people behind research outputs. Crossref vocabulary includes roles that aren’t recognised in CRediT, and vice versa. Capturing richer contributor metadata recognises contributions that may not be visible in a single author line and improves transparency around how research is produced, thereby enabling downstream systems to interpret that information more reliably. The update also offers better interoperability with CRediT, which is well recognised across the scholarly ecosystem.
Figure 2: Schema 5.5 is an expansion of Crossref contributor metadata. Members can describe contributors using Crossref’s existing contributor role vocabulary, as well as the internationally recognised CRediT taxonomy.
In turn, this strengthens metadata reuse across repositories, discovery services, funders, institutions and other infrastructure providers; and supports evaluation, reporting and discovery workflows. Better contributor metadata strengthens the connections that make up the Research Nexus.
What else is included in Schema 5.5?
Beyond the expanded contributor support, Schema 5.5 includes several additional enhancements across the metadata schema.
1. Updates to report series metadata
Support has been added for metadata elements that were previously missing from report series records, including Crossmark, funding, and licence information.
2. Posted content improvements: now including blogs and posters
Posted content includes preprints, eprints, and other types of content that have been posted to a stewarded host platform. We’re all about persistence, so it’s vital that everything registered with us be maintained. Note that accepted manuscripts are not considered posted content. Schema 5.5 refreshes posted content sub-types by introducing blog and poster.
At the same time, we are “retiring” working paper, dissertation, and report from posted-content sub-types. Over time, these have been developed into separate record types that benefit from richer, dedicated schemas.
Finally, archive locations can now also be included for posted content records.
4. Clinical trial metadata across more record types
Clinical trial information is no longer limited to journal articles and conference papers. Schema 5.5 extends support across additional content types, including books, datasets, dissertations, reports, posted content, standards, and pending publications.
Schema adoption
Taken together, the updates in our latest schema support more holistic recognition of contributions to the research and its communication, as well as greater accountability and integrity in related processes.
To support gradual adoption, Schema 5.5 maintains backwards compatibility with existing deposits. Members can continue using the current contributor_role attribute while preparing to implement the new repeatable role element. We have prepared a migration guide to help members transition to Schema 5.5.
As you prepare to adopt Schema 5.5, we encourage members to include contributor roles whenever they are available from editorial workflows and to use recognised vocabularies consistently, including CRediT roles where appropriate.
Related reading
Blog
Building better connections: the story of Crossref's metadata development